How debrid services work
Paste a link or a magnet and get back a fast direct download. How debrid services work: resolving and caching, the architecture behind them, why cache is the real secret, the business model and the legal part.
There's a kind of internet service that feels almost magical the first time. Paste a link, a magnet, a torrent file, sometimes an NZB, and the service hands back a clean, fast, direct link to download or stream. No queue, no captcha, no computer left on while the home connection does the heavy lifting.
That's the world of debrid services.
The name is a little misleading, though. "Debrid" names a bundle of things: cache, high-bandwidth servers, integration with file hosts, remote downloading, temporary storage, APIs and a convenience layer on top. These services are middlemen. They sit between the user and external file sources and turn a slow, limited, broken experience into a direct one.
The short version: a debrid service takes a link or magnet, resolves it on its own infrastructure, downloads it or reuses a copy it already has, and returns a fast HTTP link or stream. The interesting part is underneath.
Resolving and caching #
A common mistake is to picture a debrid service as a hidden streaming catalog with a neatly organized library. Most of them don't start from an editorial catalog of their own. They work from what users submit.
The user sends a file host link, a magnet, a torrent, an NZB or a URL. The system checks whether that exact content is already in its cache. If it is, the answer can be almost instant. If not, the job goes into a queue, the service downloads the file on its own servers and then makes it available.
That's why some things seem to appear immediately. The server didn't download 80 GB in three seconds. Someone asked for the same thing earlier, and the service kept a copy it could reuse.
That's the economic heart of the business: shared cache. The cost of downloading and storing a popular file once gets spread across thousands of users. An obscure old file is the opposite. It takes disk, burns bandwidth and may never be requested again. These services live by balancing retention, popularity, disk cost and traffic cost.
The basic architecture #
If I had to describe a debrid service in a simple but honest way, it would have these parts:
- Front end: a website, an app, a browser extension, or integrations with media players and download managers.
- API: almost everything goes through it. Users submit links, check status, list files, generate direct links and remove items. Real-Debrid, AllDebrid, Premiumize and TorBox all publish API documentation.
- Queue: when something isn't ready, the work has to wait its turn to be downloaded, verified, extracted and published.
- Download workers: machines that specialize in fetching content, with BitTorrent clients, multi-connection HTTP downloaders, Usenet clients or modules for specific sources.
- Cache and deduplication: the system tries not to store the same thing ten times. Torrents have hashes, and files can be identified by size, checksum, metadata or origin.
- Storage: cheap hard drives for bulk volume, SSD or NVMe for the hot cache, metadata, databases and files in progress.
- Delivery: direct HTTP, streaming with range requests, WebDAV, apps or edge servers. For video, seeking is everything: a jump to minute 50 means the server has to send that part without the device downloading the whole file first.
- Abuse control: per-user limits, per-host limits, rate limits, blocked links, takedown handling, logs, fraud checks and compliance.
None of this is exotic. The hard part is running it at scale without bleeding money on bandwidth and disks.
Why building one is harder than it looks #
Any script can download a file. A small, legal cloud downloader for personal use can be put together with common pieces like aria2, a torrent library, a queue and a database. A commercial service has a much longer list of headaches: thousands of downloads at once, avoiding useless duplication, prioritizing the hot cache, broken sources, each host's limits, secure temporary links, streaming that seeks properly, predictable speed, keeping one user from wrecking the infrastructure for everyone, deciding when to delete files, legal complaints, payments, support, fraud and chargebacks.
A typical backend would probably be split into several services. One receives the request, another normalizes the link, another checks the cache, another schedules the download, another runs it, another verifies integrity, another publishes the file and signs the URLs, and another keeps stats and quotas.
This could run on Kubernetes, but it doesn't have to. Plenty of companies in this space could do fine with dedicated servers, simple queues, solid databases and their own automation.
The real secret is cache #
Cache is the difference between a profitable service and a machine that burns money.
Imagine a hundred users asking for the same 40 GB file. Downloading it a hundred times would be stupid. Downloading it once and serving it a hundred times is where the math starts to work. That's why these services love popular content.
I can't know the exact retention policy of any company, since none of them publish it. But operationally it's hard to imagine it being very different from this: content that gets requested a lot stays longer, recent requests get priority, rare content expires quickly, broken or incomplete files get removed, fast NVMe is reserved for hot data, big HDD pools hold the cold stuff, metadata lives in a fast database, and user links expire.
Where the content comes from #
Debrid services usually don't go out looking for content like an editor or a streaming platform. They receive input from users. The user supplies a link, magnet, torrent or NZB, and the service tries to fetch it from that source or return a cached copy.
There are three main kinds of source. File hosts are websites that store files and often limit speed, show captchas or push paid accounts; the debrid service resolves the link and offers a more convenient way to get it, which is the classic debrid model. Torrents turn the service into a simplified seedbox: it downloads in a data center and delivers over HTTP or streaming, instantly if the torrent is already cached. Some services also accept NZBs, which means the download comes from Usenet servers, a different world with its own providers, retention and indexers.
Infrastructure, roughly #
There's no universal number here. Real-Debrid, AllDebrid, Premiumize, TorBox, put.io and Seedr don't publish their infrastructure. What we can look at is comparable services that do publish specs, like seedbox providers. Whatbox lists hard drive plans on a shared 40 Gbps connection and NVMe plans on a shared 100 Gbps connection. Ultra.cc advertises a 50 Gbps network. Those numbers are capacity shared by all the users on the network.
For storage there are two worlds: large hard drives (many terabytes per server) for bulk volume, and smaller but fast NVMe for hot cache and quick operations. CPU usually isn't the bottleneck unless there's video transcoding involved. For direct downloads and direct streaming, network and disk matter far more.
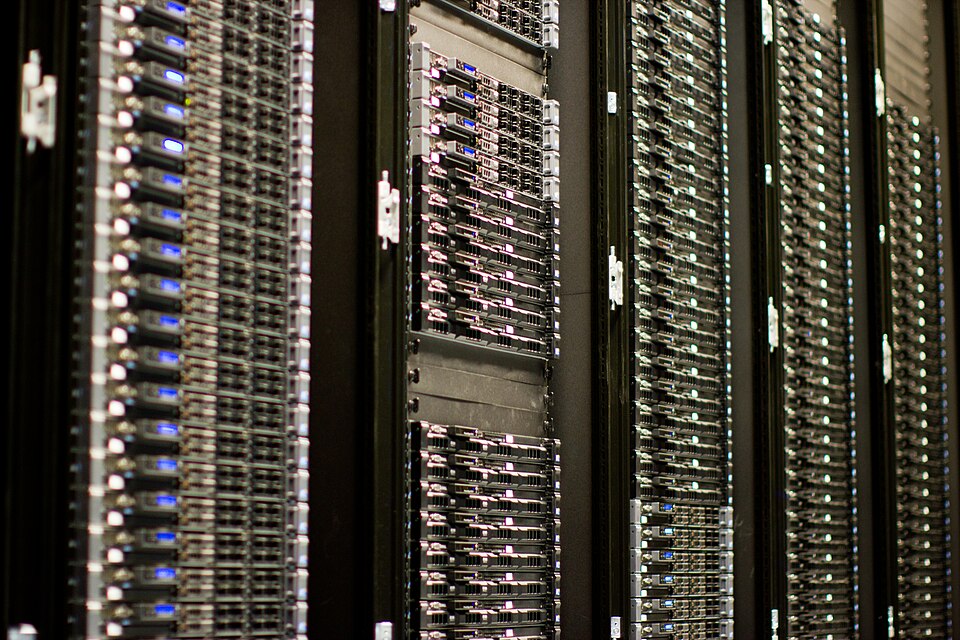
A large commercial service runs on a fleet of servers. Some nodes download, some store, some serve, some handle metadata, and some sit at the edge to deliver traffic. Where they run comes down to cheap bandwidth, good international connectivity and the jurisdiction the company operates under, which shapes what legal obligations it has.
Why people pay #
The money pays for three hard things: bandwidth, storage and convenience. It also pays for not maintaining a server, configuring a torrent client, dealing with file hosts, leaving a PC on, suffering with residential upload speeds, solving captchas or building a media pipeline.
It's the gap between "I could do this myself" and "do I really want to run this?" To a technical person, debrid can look like laziness. Operational laziness is a perfectly valid product, and half of the SaaS world exists because of it.
Debrid, seedbox, cloud downloader, VPS #
An honest comparison, as I see it:
- Debrid: best for fast links, shared cache and cheap convenience inside media apps.
- Seedbox: best for control, private trackers, FTP or SFTP access and running your own apps like Plex or Jellyfin. It's closer to a personal remote server.
- put.io, Seedr, Bitport: a simple cloud downloader with a temporary library, like a downloads folder in the cloud.
- Your own VPS: full control, all the maintenance, and you live with the consequences.
The business model #
The model only works if most users consume less than they think they will. Like any "unlimited" or "almost unlimited" service, it's a statistical game. Many people pay and barely use it. A few hammer it. The service uses limits, quotas, short retention, fairness rules, queues, variable speeds or host-specific restrictions to keep everything alive.
The margin probably comes from reused cache, controlled overselling, temporary storage, negotiated bulk traffic, plans with explicit or hidden limits, light users subsidizing heavy ones, and a lot of automation to keep support costs down. If every subscriber suddenly decided to download tens of terabytes a month, the math would break fast.
The legal part #
There's no point pretending this market is squeaky clean. Debrid services, seedboxes and cloud downloaders have legitimate uses, and they're also widely used to get copyrighted material.
The technology is neutral. Downloading a Linux ISO through a debrid service isn't the same as downloading a film you have no license for. But a neutral tool doesn't erase legal responsibility. Operators deal with takedowns, abuse reports, payment processors, copyright pressure and unstable hosts.
For users, the rule is simple: if the content needs a subscription, a purchase or a license, using a middleman to get around that can land anyone in ugly legal territory. And for anyone thinking of running a service like this, doing it without legal advice and a real abuse policy is asking for trouble.
Why I find it interesting #
Debrid puts heavy infrastructure behind an extremely simple experience. From the outside it's "paste a link, get a file". Underneath it's queues, cache, networking, disks, quotas, APIs, workers, storage and cost engineering.
It also shows something a bit uncomfortable about the internet: sometimes the content is exactly the same, and the whole difference between a bad experience and a good one is the delivery layer. The file is already somewhere. The problem is reaching it without wasting time, patience and bandwidth, and that's exactly what these services sell. It isn't always elegant or defensible, but technically I find it fascinating.
That's it. See you.
Sources #
- Real-Debrid API documentation: https://api.real-debrid.com/
- AllDebrid API documentation: https://docs.alldebrid.com/
- Premiumize API documentation: https://www.premiumize.me/api
- TorBox API documentation: https://api-docs.torbox.app/
- Whatbox plans: https://whatbox.ca/plans
- Ultra.cc: https://ultra.cc/
- Seedbox, Wikipedia: https://en.wikipedia.org/wiki/Seedbox