How Usenet serves files
Usenet was built to pass messages around, never files. How people turned files into articles anyway: yEnc, alt.binaries, the many RAR files, PAR2 repair, NZB files, retention, and how it compares to BitTorrent.
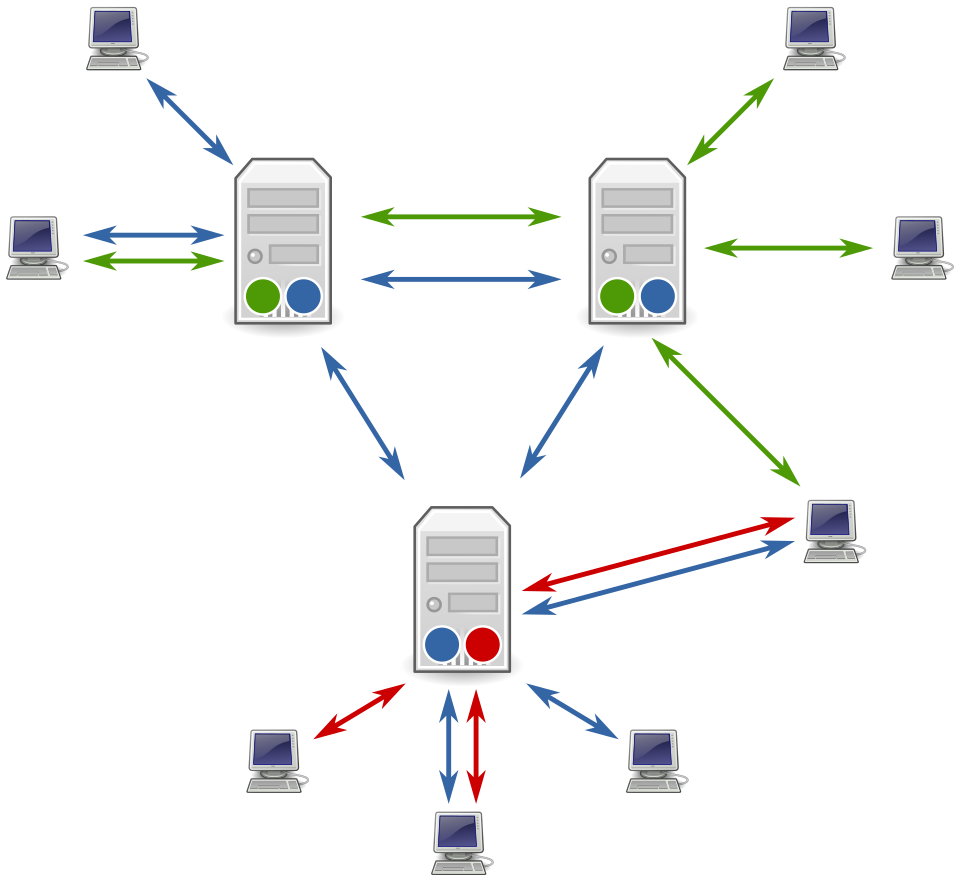
There's something I love about Usenet: it was never meant to be a file download system. Its original job was simpler and, in a way, more elegant. It distributed messages. Text, discussions, forums before forums existed. People posted to groups, servers passed articles to each other, and newsreaders downloaded the messages and the replies.
Then, as always happens on the internet, someone looked at that system and started putting files in it.
Usenet doesn't serve files the way HTTP, FTP or BitTorrent do. It was never designed to say "here's video.mkv, download it". What it does is store and distribute articles, using a protocol called NNTP. So the trick was to turn files into articles.
The file never travels in one piece #
When someone posts a big file to Usenet, it isn't uploaded as one block. That would be impractical. The file gets split into many small pieces, each piece gets encoded into something that can live inside an NNTP message, and those messages get posted to specific newsgroups, usually under alt.binaries.*. One file can turn into hundreds or thousands of separate articles.
Simplified, the trip looks like this:
- The original file is split into parts.
- Each part is encoded into a message-friendly format.
- The parts are posted as NNTP articles.
- Usenet servers store and pass them along.
- A client downloads them, decodes them and puts the file back together.
So the server isn't "serving a file" in the usual sense. It serves articles, and the client knows that those articles, together, make a file.
yEnc #
In the early days, encodings like uuencode1 were common. Later, yEnc became the de facto standard for binaries on Usenet.
yEnc takes binary data and encodes it so it can travel inside a Usenet message, wasting much less space than the older methods. Across millions of messages and huge files, that difference adds up.
Each chunk of the file is encoded with yEnc and becomes the body of one article. Look at it raw and it's nonsense. To a Usenet client, it's a perfectly good piece of something bigger. Normal users never see any of this, because the download client handles it.
The alt.binaries groups #
File sharing on Usenet became tied to the alt.binaries.* hierarchy, with groups like alt.binaries.multimedia, alt.binaries.sounds, alt.binaries.pictures and alt.binaries.ebooks. The name says what they're for: binary content, not conversation.
Technically a binary could go to other groups too, if the server allowed it. In practice binaries concentrated in these hierarchies, and that helped servers decide what to accept, what to reject and how long to keep each kind of content. Keeping years of text discussions is easy. Keeping years of large files takes a lot of disk, a lot of bandwidth and a lot of administrative discipline.
Why so many RAR files #
Anyone who has touched Usenet binaries has seen sets like file.part001.rar, file.part002.rar, file.part003.rar and so on. That isn't random. RAR made it easy to split a big file into smaller volumes, so a failure didn't necessarily mean downloading everything again. The volumes also fit nicely into a workflow where everything was already being cut into small pieces.
So the content was often compressed and split into RAR volumes first, then cut into smaller pieces, encoded with yEnc and posted as NNTP articles. It looks excessive, and each layer solves a real problem.
PAR2 and missing pieces #
Usenet doesn't guarantee that every article arrives intact on every server. One server misses a part. Another expires older articles. Another has corruption. Another doesn't carry the group at all.
That's what PAR2 files are for. They're recovery files that hold parity data, a kind of mathematical spare material that can rebuild missing or damaged pieces. A set might include file.vol000+01.par2, file.vol001+02.par2 and so on next to the RAR volumes. If one or two pieces are missing, the client uses the PAR2 files to repair the set. There's a limit, of course: if too much is gone, nothing fixes it.
Still, this repair layer is one of the reasons Usenet worked so well for big files. Without PAR2, downloading large binary posts would be a lot more frustrating.
NZB files #
Now the central piece: the NZB file.
Picture a file split into 3,000 NNTP articles. Nobody is going to find all of those by hand. An .nzb file solves that. It's an XML index that lists the Message-IDs of every article needed to rebuild a given file. The client reads it and goes: right, I need to fetch these 3,000 articles from the server. Then it connects and asks for them one after another, joins them, decodes them, repairs them if needed and delivers the final file.
In short: the NZB is the map of the articles, NNTP is the protocol used to fetch them, the Usenet server is where they're stored, and the client is the software that downloads, repairs and rebuilds everything.
The NZB doesn't contain the file. It contains instructions for finding the file's pieces inside Usenet, a lot like the difference between a .torrent file and the data it points to.
What the server knows about it #
Most of the time, it doesn't need to know what it's delivering. A client asks for something like this:
ARTICLE <some-message-id>The server sends back the matching article, whose body is an encoded chunk, usually yEnc. To the server it's just a message. To the client it's part of a larger file. Most of the intelligence lives in the clients and indexers, not in each server.
Commercial providers and retention #
Today, when people talk about downloading from Usenet, they almost always mean commercial providers. These sell access to servers with high retention, high speed, many simultaneous connections and TLS.
The key word is retention: how long the provider keeps articles available. Keeping years of text is cheap. Keeping years of binaries takes massive infrastructure, because the volume in binary groups is enormous. When a provider advertises thousands of days of binary retention, it means it stores old binary articles for many years, and that's expensive.
That's why modern binary Usenet isn't a garage hobby. A text-only server runs fine on a small VPS. A serious binary server needs huge storage, heavy bandwidth and a very clear abuse policy.
Usenet and BitTorrent #
People compare Usenet with BitTorrent all the time, and the logic is very different:
| Question | BitTorrent | Usenet |
|---|---|---|
| Where the download comes from | Other users | NNTP servers |
| What keeps a file available | Seeders | The provider's retention |
| Where the decentralization lives | The swarm of peers | The old federation of servers |
| Uploading while downloading | Usually yes | No |
In practice Usenet feels more like downloading from a premium server, even though underneath there's that old structure of articles, groups, propagation and retention.
Running one #
Technically it's possible, but it depends a lot on the kind of server.
A text-only NNTP server is completely realistic. Install something like INN,2 create a few groups, control access, set up TLS and point any newsreader at it. For learning, a small community or an internal project, it's a great experiment.
A public or federated binary server is a different beast. It means huge storage needs, heavy bandwidth, short or expensive retention, spam, abuse, problematic content, legal notices, authentication, peering, queues and constant monitoring. Once a server accepts alt.binaries.*, data growth gets brutal fast. A cheap VPS left alone won't handle it.
For learning, the smart move is a small private group like local.binaries.test. Post small files, see how yEnc works, generate an NZB, download it with a client, and follow the whole flow without drowning in terabytes and legal headaches.
The short version #
Usenet serves files without really being made for it. It stores articles. People learned to compress and split files into RAR volumes, encode the pieces with yEnc, post them as NNTP articles, index them with NZBs, and then download, repair with PAR2 and rebuild the file on the other end.
It's old, strange and a little underground, and it's also incredibly clever. The modern web hides its complexity behind polished buttons. Usenet leaves the gears in plain sight, and I think that's a big part of why it's still so interesting.
Notes
-
uuencode was written at Berkeley in 1980 to send binary files over UUCP, which only carried plain text. It turns every 3 bytes into 4 printable characters, so the output is roughly a third bigger than the file. yEnc's overhead is a few percent. ↩
-
INN, short for InterNetNews, was written by Rich Salz and released in 1991. It's still maintained, and it's still the usual choice for a self-hosted news server. ↩